

Distribution Matching Distillation (DMD): how a slow diffusion model becomes a one-step image generator.
Diffusion models make gorgeous images, but they are slow. They denoise step by step, often 25 to 50 passes through a giant network for a single picture. That kills real-time and on-device use. DMD fixes this by distilling that multi-step teacher into a ONE-step student generator.
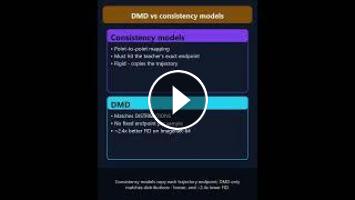
The clever part: DMD does not force the student to copy the teacher's exact denoising path (that is what consistency models do). It only asks that the cloud of images the student produces looks like the teacher's cloud. It scores each generated image two ways - with the frozen teacher (the real distribution) and with a small "fake" critic trained on the generator's own outputs - and the training gradient is just the difference of those two scores, an approximate KL divergence.
The numbers: original DMD hits 2.62 FID on ImageNet-64 at 20 FPS, about 100x fewer network evaluations. DMD2 drops the expensive teacher dataset, adds a GAN loss, supports 1 to 4 steps, and reaches 1.28 FID - beating its own teacher at roughly 500x less inference cost. Its SDXL 4-step LoRA is a drop-in adapter for existing Stable Diffusion XL workflows.
Reach for DMD when latency and cost matter and you have a strong teacher to distill. Think twice if you have no teacher or cannot afford the extra distillation training.
Did this make DMD click? Follow for plain-English GenAI breakdowns.
#GenAI #DiffusionModels #MachineLearning #AIEngineering #StableDiffusion
- Категория
- AI Картинки
Выполните вход или зарегистрируйтесь для отправки комментария.
Комментариев нет.
Следующее
Auto
-
07:30

Adversarial Diffusion Distillation: High Fidelity Real Time Image Synthesis | Stability AI
-
2 Robot Có Thể Thay Thế Toàn Bộ Nhân Viên Giữ Xe?
-
05:19
Diffusion Forcing: Unifying Autoregressive and Diffusion Models #genai #llm #ai
-
05:22
Stable Diffusion Hoạt Động Thế Nào? Bí Mật Nằm Ở Đây!
-
07:39
Flow Matching Explained: The Fast Generative AI Behind Flux and Stable Diffusion 3
-
05:44
Consistency Models Explained: Generate Images in One Step Instead of Fifty #genai #ai #llm
-
01:40
LoRA models #lora #ai #genai #googlestudents #shortvideo #llm #stablediffusion
-
03:06
Stable Diffusion Tạo Ảnh Như Thế Nào? Giải Mã 50 Bước Từ Một Seed!
-
05:22
DeepCache Explained: Speed Up Stable Diffusion by 2-4x #genai #llm #ai
-
30:25
The Math Behind Stable Diffusion 3 (Flow Matching Explained)
-
13:39

Best AI Tools For Research in 2026 (Beats ChatGPT & 0% Detection)
-
00:37

3 AI tools for programmers
-
00:55

The Best AI Tools For Content Creators
-
00:58

7 AI tools you NEED to try!
-
00:12

Best AI Tools For Hacker
-
11:15

10 Best AI Tools You MUST Try in 2025
-
00:28

The most popular AI tools right now... which one is best?
-
00:36

Best Free AI Tools for Research Papers & Essays | Write Smarter!
-
14:34

Google's NEW AI Tools Will BLOW YOUR MIND | Google I/O 2026
-
00:18

Best FREE AI Tools for Designers | Boost Your Creativity #ai #aitools #graphicdesign #designer
 Загрузка...