

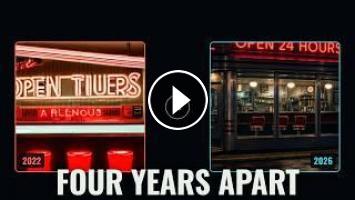
We gave the same three prompts to every AI image model we could run, from 2022 to today, and lined the
results up on a timeline. The same sentences go from a melted, misspelled mess to a photo that passes
without a second look — in about four years.
The three prompts, held identical: a SIMPLE one (a red apple on a table), a MEDIUM one (two hands holding
a small bird — the pose AI was famous for botching), and a HARD one (a neon sign that has to spell "OPEN
24 HOURS," with exactly three stools). Same prompt, one try each, no cherry-picking.
What the timeline shows: the simple prompt was basically solved years ago — the floor was already high.
The hands healed: the early models give you soft, wrong, often the wrong number of hands; by 2024 they
cradle the bird like a photograph. And in-image text — long the giveaway — snaps into focus by 2024:
the neon goes from gibberish to a clean "OPEN 24 HOURS."
And it's not just the spelling. That hard prompt asked for exactly three stools — and the early models
(2022–23) gave you a whole row of five or six. But the newest ones, from 2024 on, nail it: exactly three.
Even counting — long the thing AI was worst at — quietly got solved. The tells are nearly gone; soon "is
this real?" won't have an answer.
Method & honesty (this is the whole point):
- The MODERN models are our own runs, under a fixed protocol: the same prompt verbatim, ONE try (not
best-of-twenty), seed 42 where a model exposes one (gpt-image-1 doesn't), default settings, a
representative result — not a cherry-picked best. Each is logged with model, version, seed, and prompt.
Models shown: Stable Diffusion 1.5 (2022), SDXL (2023), Stable Diffusion 3.5 + FLUX.1 (2024), FLUX 1.1
pro (2024), Ideogram v3, gpt-image-1, FLUX.2 (2025), and gpt-image-2 (2026, the live frontier).
- The OLDER models (DALL·E 1/2/3, VQGAN+CLIP, GLIDE, Imagen, Midjourney) we could not run — so those are
EXAMPLE IMAGES WE FOUND: the labs' own showcase shots, on different prompts, not re-run. And remember
every vendor sample is a cherry-picked best-of-many. There's an irony there: the model that started this
whole era — DALL·E, 2021 — had its entire line switched off in May 2026. The thing that launched it is
already a museum piece.
This video uses a synthetic (AI) voice. The modern images are generated by us via Replicate / OpenAI
(logged); the historic images are attributed sample shots from the labs' papers and announcements (DALL·E,
GLIDE, Imagen) and Wikimedia Commons (DALL·E 2/3, VQGAN+CLIP, Midjourney's "Théâtre D'opéra Spatial") —
see the pinned comment for credits.
Music: "Between the Lines" by Ondrosik — Creative Commons CC0 1.0. https://links.al/5Bu · Promoted by Audio Library: https://links.al/youtube
#aiart #aiimages #midjourney #dalle #toscale
Chapters:
0:00 The same sentence, four years apart
0:21 The test: three prompts, one fair rule
0:39 Simple: the floor was already high
0:51 Medium: the hands heal
1:07 Hard: the neon learns to spell
1:20 Even the count fell
1:31 One try, not best-of-twenty
1:41 The model that started it all
1:58 Nightmare to photo
Method: modern models are our own runs — same prompt, ONE try, no cherry-picking (seed 42 where exposed).
Older models we couldn't run, so those are the labs' own showcase samples (a different prompt, not re-run,
and themselves cherry-picked). Image credits: DALL·E/GLIDE/Imagen samples © OpenAI/Google (editorial);
DALL·E 2/3, VQGAN+CLIP, Midjourney "Théâtre D'opéra Spatial" via Wikimedia Commons (PD / CC BY 4.0).
- Категория
- AI Картинки
Выполните вход или зарегистрируйтесь для отправки комментария.
Комментариев нет.
Следующее
Auto
-
Same Prompt, Same Seed — Five Different AI Images. Why? #shorts
-
2 Robot Có Thể Thay Thế Toàn Bộ Nhân Viên Giữ Xe?
-
05:22

Stable Diffusion Hoạt Động Thế Nào? Bí Mật Nằm Ở Đây!
-
05:08
Most Popular AI Websites (2022 - 2026)
-
09:08
ChatGPT Vs Gemini 2022 - 2026 | Version Extendida
-
03:06
Stable Diffusion Tạo Ảnh Như Thế Nào? Giải Mã 50 Bước Từ Một Seed!
-
51:08
NGƯỜI VIỆT GÓP SỨC XÂY DỰNG GROK-3: Hành Trình Từ Huy Chương IMO Đến ĐỈNH CAO AI Thế Giới
-
00:10
AI Animation 2022 vs 2024 #ai #comfyUI #stablediffusion
-
00:19
MÌNH THAY THẾ ĐỐNG DÂY DUPONT BẰNG BREADBOARD #huyaiautomation
-
Stable Diffusion (2022): The AI Image Model Given Away Free While DALL-E Had a Waitlist
-
13:39

Best AI Tools For Research in 2026 (Beats ChatGPT & 0% Detection)
-
00:37

3 AI tools for programmers
-
00:55

The Best AI Tools For Content Creators
-
00:58

7 AI tools you NEED to try!
-
00:12

Best AI Tools For Hacker
-
11:15

10 Best AI Tools You MUST Try in 2025
-
00:28

The most popular AI tools right now... which one is best?
-
00:36

Best Free AI Tools for Research Papers & Essays | Write Smarter!
-
14:34

Google's NEW AI Tools Will BLOW YOUR MIND | Google I/O 2026
-
00:18

Best FREE AI Tools for Designers | Boost Your Creativity #ai #aitools #graphicdesign #designer
 Загрузка...