

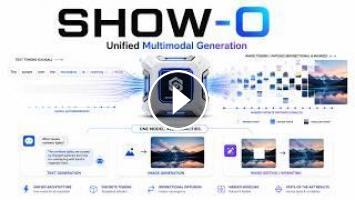
Show-o introduces a powerful new direction for unified multimodal AI: one transformer model that can understand text, generate images, answer visual questions, and perform image editing inside a single architecture.
Instead of relying on traditional continuous diffusion models or slow autoregressive image generation, Show-o uses masked discrete diffusion. This allows the model to generate image tokens in parallel, making inference much faster while still preserving strong visual quality.
In this video, we break down how Show-o works, including its unified transformer design, causal attention for text, bidirectional attention for images, masked token prediction, inpainting capability, and why discrete diffusion could become an important alternative for next-generation multimodal systems.
You will learn:
↳ What Show-o is and why it matters
↳ How masked discrete diffusion works
↳ Why parallel image generation is faster than autoregressive decoding
↳ How one checkpoint handles text, image, VQA, and editing tasks
↳ The difference between Show-o, diffusion models, and autoregressive multimodal models
↳ Why unified multimodal generation is becoming a major AI research direction
Show-o shows that future AI systems may not need separate models for language, vision, generation, and editing. Instead, a single unified transformer may be able to handle all modalities efficiently.
#ShowO #MultimodalAI #GenerativeAI #DiffusionModels #AIResearch #TransformerModels #TextToImage #VisionLanguageModel #AIGeneration #MachineLearning
- Категория
- AI Картинки
Выполните вход или зарегистрируйтесь для отправки комментария.
Комментариев нет.
Следующее
Auto
-
00:17

You Don't Need To Show Your Face
-
06:30
Stable Diffusion AI | Stable Diffusion Explained | In Hindi | Text-To-Image Generation |ALGOBRAIN AI
-
00:59
ChatGPT, Show Me an Apple
-
10:46
AI-901 Azure AI Fundamentals Lesson 12: Image Generation Explained Fast
-
00:35
ChatGPT, Show Me Rice
-
36:23
The Future of Building with AI: Multimodal Agents, Generative Media, and Open Models - O. Sanseviero
-
09:21
Seedance 2.5 FREE & UNLIMITED for 365 Days! Fast Generation + Create Long AI Videos | Topview AI
-
01:29
Multimodal AI Explained: How Models Understand Images, Audio and Text
-
00:38
How Does AI Image Generation Work? — Diffusion Models Explained #midjourney #dalle #diffusion
-
07:39
Flow Matching Explained: The Fast Generative AI Behind Flux and Stable Diffusion 3
-
13:39

Best AI Tools For Research in 2026 (Beats ChatGPT & 0% Detection)
-
00:37

3 AI tools for programmers
-
00:55

The Best AI Tools For Content Creators
-
00:58

7 AI tools you NEED to try!
-
00:12

Best AI Tools For Hacker
-
11:15

10 Best AI Tools You MUST Try in 2025
-
00:28

The most popular AI tools right now... which one is best?
-
00:36

Best Free AI Tools for Research Papers & Essays | Write Smarter!
-
14:34

Google's NEW AI Tools Will BLOW YOUR MIND | Google I/O 2026
-
00:18

Best FREE AI Tools for Designers | Boost Your Creativity #ai #aitools #graphicdesign #designer
 Загрузка...