

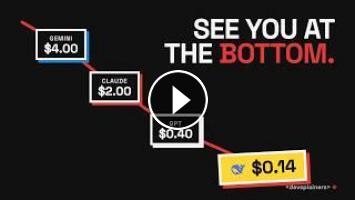
DeepSeek V4 Flash reads a million-token prompt for about 14 cents. The same request runs roughly $2 on Claude Sonnet 5 and over $4 on Gemini 3.1 Pro.
This is the animated breakdown of how DeepSeek got the price of long context that low: sparse attention. We cover why long prompts cost a fortune in the first place, what the Lightning Indexer does, how compressed sparse attention and heavily compressed attention split your prompt into three views, and the workloads where the whole trick breaks without warning.
Get the hotter takes in your inbox every Tuesday: https://devsplainers.com/takeouts/
CHAPTERS
00:00 The $19 API bill that should have cost four figures
00:36 Why long prompts cost a fortune (attention and the memory bill)
01:48 The skip: most attention math returns nothing
02:54 How DeepSeek built it (summaries, Lightning Indexer, the skim lane)
04:28 Native Sparse Attention and the skeptic's six-month deadline
05:12 The rest of the bill: MoE, 4-bit weights, and the rate card
06:31 The catch: where sparse attention answers wrong with confidence
07:43 What cheap long context changes for you
WHAT IS SPARSE ATTENTION?
Standard attention compares every word in your prompt against every other word, so doubling the prompt quadruples the work. Measure where that attention actually lands and a handful of earlier words carry nearly all the weight while the rest sit near zero. Sparse attention predicts which words matter, cheaply, then spends the expensive math only on those. The hard part is doing the prediction without burning the savings, and without missing the one line that mattered. DeepSeek's answer, published in the V4 paper, runs three views of your prompt at once: 4:1 learned summaries, a tiny scorer called the Lightning Indexer that picks the top 512, and a 128:1 skim lane the model reads every single time so nothing goes fully invisible. Send ten thousand tokens or a million and the expensive part reads roughly the same small pile.
COVERED IN THIS VIDEO
- Why attention cost grows with the square of the prompt length
- The KV cache memory bill and why it raises the price per customer
- Attention concentration: the empirical result sparse attention is built on
- Why fixed-window shortcuts and post-hoc pruning both failed
- Compressed sparse attention (CSA) and heavily compressed attention (HCA)
- The Lightning Indexer and the top-512 selection
- DeepSeek V4 Flash pricing: $0.14 in, $0.28 out, and near-free cached input
- How that compares to GPT-5.6 Luna, Claude Sonnet 5, and Gemini 3.1 Pro
- Mixture of experts, 4-bit weights, and a draft model on top of the attention win
- Where sparse attention fails: diffuse aggregation, exact strings, short prompts
- What cheap long context does to the way developers actually work
RELATED DEVSPLAINERS VIDEOS
KV cache, explained: https://youtu.be/WQYhwNBWF-I
Context windows, explained: https://youtu.be/5ikn6shbm6w
Speculative decoding, explained: https://youtu.be/YFwsSaWerDY
What AI coding actually costs: https://youtu.be/lAwb6fFmfA8
SOURCES
- DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence (arXiv:2606.19348)
- Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention (arXiv:2502.11089)
- Efficient Streaming Language Models with Attention Sinks (arXiv:2309.17453)
- The Sparse Frontier: Sparse Attention Trade-offs in Transformer LLMs (arXiv:2504.17768)
- DeepSeek API pricing and the DeepSeek-V4-Flash-0731 model card
- OpenAI, Anthropic, and Google Gemini public rate cards
- OpenRouter model rankings
- Artificial Analysis AA-Omniscience hallucination benchmark
- Reuters on DeepSeek's May 2026 price cut
- vLLM and SGLang sparse attention implementations and profiling
#DeepSeek #SparseAttention #LLM #AIEngineering #DeepSeekV4
- Категория
- Заработок на AI
Выполните вход или зарегистрируйтесь для отправки комментария.
Комментариев нет.
Следующее
Auto
-
2 Robot Có Thể Thay Thế Toàn Bộ Nhân Viên Giữ Xe?
-
00:19

How China’s Automation Boom Is Cutting Manufacturing Costs
-
1:07:12
Ground your Agentic AI with Tools and Memory (Full Tutorial)
-
00:37
Saying Please to ChatGPT Costs Millions. He Does It Anyway | Steve King #podcastclips
-
01:42
Man Uses ChatGPT to Save Tiny Bird Shaking On Ground | The Dodo
-
01:03
колько весит сервер для запуска DeepSeek-V4? #deepseek #chatgpt #ai #nvidia #pc #ram
-
51:08
NGƯỜI VIỆT GÓP SỨC XÂY DỰNG GROK-3: Hành Trình Từ Huy Chương IMO Đến ĐỈNH CAO AI Thế Giới
-
05:22
Stable Diffusion Hoạt Động Thế Nào? Bí Mật Nằm Ở Đây!
-
03:06
Stable Diffusion Tạo Ảnh Như Thế Nào? Giải Mã 50 Bước Từ Một Seed!
-
00:19
MÌNH THAY THẾ ĐỐNG DÂY DUPONT BẰNG BREADBOARD #huyaiautomation
-
13:39

Best AI Tools For Research in 2026 (Beats ChatGPT & 0% Detection)
-
00:37

3 AI tools for programmers
-
00:55

The Best AI Tools For Content Creators
-
00:58

7 AI tools you NEED to try!
-
00:12

Best AI Tools For Hacker
-
11:15

10 Best AI Tools You MUST Try in 2025
-
00:28

The most popular AI tools right now... which one is best?
-
00:36

Best Free AI Tools for Research Papers & Essays | Write Smarter!
-
14:34

Google's NEW AI Tools Will BLOW YOUR MIND | Google I/O 2026
-
00:18

Best FREE AI Tools for Designers | Boost Your Creativity #ai #aitools #graphicdesign #designer
 Загрузка...